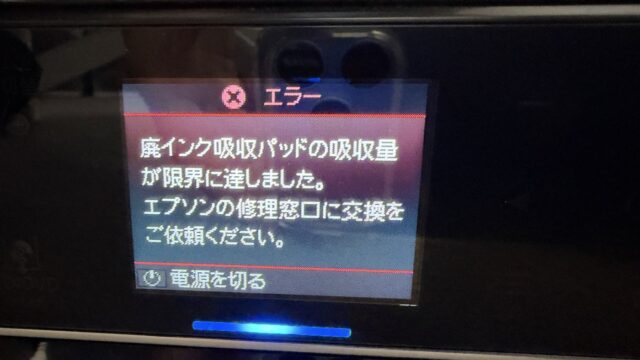
[Free] How to Clear the EPSON EP-804A Waste Ink Pad Error with the Open-Source EWR Tool
I cleared the waste ink pad error on an EPSON EP-804A for free with the open-source EWR tool: the startup-crash fix, a dry run, an EEPROM backup, and real logs.
I cleared the waste ink pad error on an EPSON EP-804A for free with the open-source EWR tool: the startup-crash fix, a dry run, an EEPROM backup, and real logs.
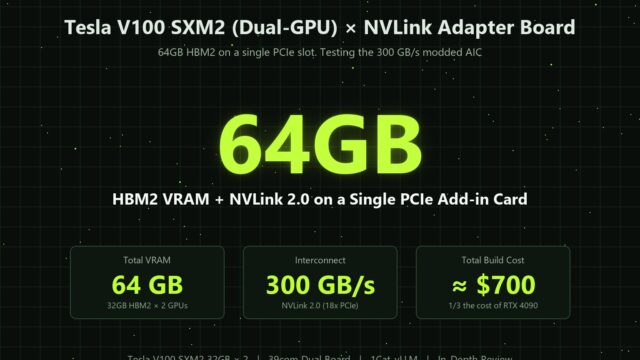
In-depth technical analysis of the 39com Dual Tesla V100 SXM2 NVLink adapter board. 64GB HBM2 and 300 GB/s NVLink on a single PCIe slot via PLX switch. Cooling mods, 1Cat-vLLM benchmarks, and complete build guide.
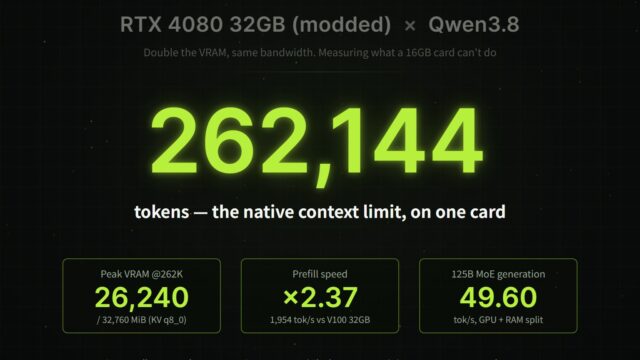
In-depth testing of a modded RTX 4080 32GB from China: Qwen3.8-27B Q8_0 fits fully in VRAM at 22.47 tok/s, while the native 262,144-token context runs in 26,240 MiB with q8_0 KV cache. Generation matches the Tesla V100 32GB, but prefill is 2.4–3.2x faster. Also covers running the 125B Qwen3.8-Flash-Next MoE offloaded to system RAM, MiniMax H3 video generation, and simulated 16GB/24GB limits.
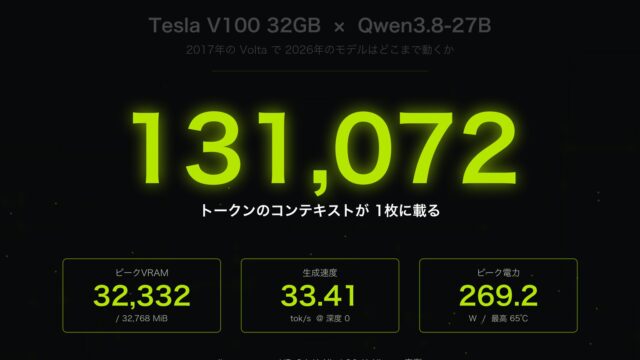
Benchmarking Qwen3.8-27B on a 2017 Tesla V100 32GB. 33.41 tok/s on Q4_K_XL, and a 131,072-token context fits in 25,264 MiB on one card. Plus the KV-quantization CPU fallback and why --reasoning-budget 1024 decides whether it is practical.
We benchmark Qwen 3.6 on a used Tesla V100 32GB (~$900): 98.8 tok/s on MoE 35B, great value, but prebuilt llama.cpp dropped Volta - build from source.
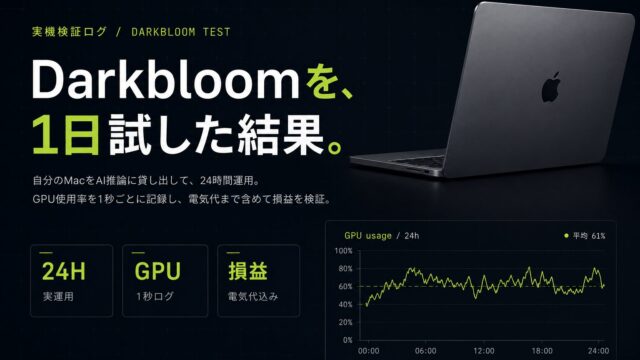
I ran Darkbloom, which pays you to serve AI inference on an Apple Silicon Mac, for a full day. The calculator promised $75/month, but I actually earned $0.60/day. Here's the honest profit-and-loss with GPU logs and measured power.
Hi, this is Shichinomiya-san (@shichinomiya_s). When you use AI agents like Claude Code or Cursor, one thing quietly adds up: token cost. Every time you have them read logs, return huge JSON, or ingest whole files, the context balloons and…
Hi, this is Shichinomiya-san (@shichinomiya_s). Last time I measured Headroom, which claims “95% token reduction”. This time I tested ADHD, another fast-rising project on GitHub (700+ stars in ~9 days, featured by The New Stack) — a skill for Claude…
Hi, this is Shichinomiya-san (@shichinomiya_s). Last time I tested how far you can push Qwen as a local LLM on a GTX 1080Ti. This time I ran the new Qwen 3.6 on an Apple M1 Max (64GB unified memory) and…
Hello, this is Shichinomiya (@shichinomiya_s). This time, I ran a full benchmark to see how far the latest local LLM “Qwen 3.5 9B” (released in 2026) can go on the legendary 2017 GPU: the NVIDIA GeForce GTX 1080 Ti. If…