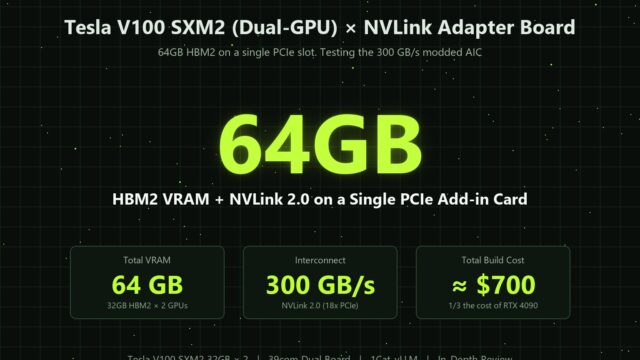
Dual Tesla V100 SXM2 on a Single PCIe Slot: 64GB VRAM & 300 GB/s NVLink Tested — Is This $700 Setup Worth It?
In-depth technical analysis of the 39com Dual Tesla V100 SXM2 NVLink adapter board. 64GB HBM2 and 300 GB/s NVLink on a single PCIe slot via PLX switch. Cooling mods, 1Cat-vLLM benchmarks, and complete build guide.