Generative-AI Lab

Put AI to the test.

A hands-on lab for the fast-moving world of generative AI. New models, tools, and services — put to work and measured for real: not spec sheets or hype, only what I verified with my own hands.

20 experiments
LLM MLX / Ollama
2026.09.17 last updated

Latest experiment

View all logs →

All logs

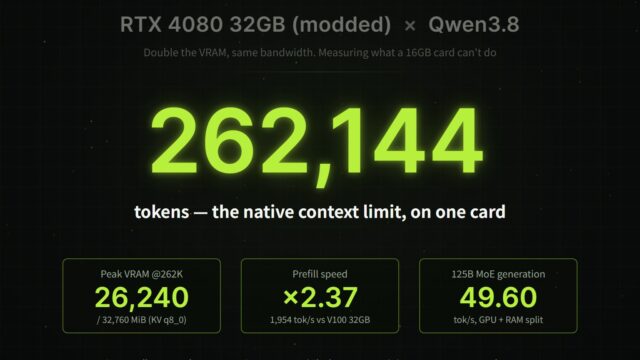
Modded RTX 4080 32GB Benchmarked: Qwen3.8-27B at 262K Context, 125B MoE, and MiniMax H3 Video — What 32GB Actually Delivers

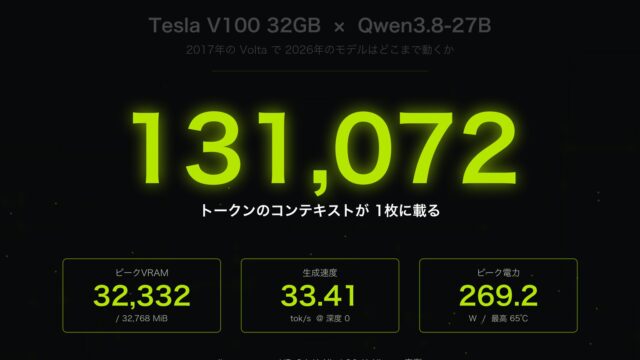
In-depth testing of a modded RTX 4080 32GB from China: Qwen3.8-27B Q8_0 fits fully in VRAM at 22.47 tok/s, while the native 262,144-token context runs in 26,240 MiB with q8_0 KV cache. Generation matches the Tesla V100 32GB, but prefill is 2.4–3.2x faster. Also covers running the 125B Qwen3.8-Flash-Next MoE offloaded to system RAM, MiniMax H3 video generation, and simulated 16GB/24GB limits.