It’s been a while since my last IT-related post. It really has been a long time.
In this article, I’ll be testing local LLMs on what can only be described as a fossil GPU: the GeForce GTX 1080 Ti.
With the generative AI boom, there’s a common perception that running LLMs locally requires a high-end GPU like the RTX 4090 or RTX 5090.
So I wanted to find out just how far you can push a legacy GPU like this one.
How to Run Local LLMs
I initially assumed you’d need a Linux environment and some heavy setup, but it turns out it’s surprisingly easy these days.
There’s a great piece of software called LM Studio, which is what I used for this test.
Test Environment
| CPU | AMD Ryzen 9 7950X 16C32T |
| RAM | DDR5 64GB (32GB *2) |
| GPU | Geforce GTX 1080 Ti |
| SSD | Samsung PM963 1.92TB |
| OS | Windows 11 24H2 |
Two years ago, I upgraded from a Ryzen 9 3950X to a 7950X, including the move to DDR5. This PC is a mix of battle-hardened parts that have been reused and passed down over the years.
The 750W power supply is now in its 10th year (scary). I really should replace it soon…

Models Tested
For the test models, I used the currently popular DeepSeek-R1 series. I ran each parameter size and compared their performance.
- DeepSeek-R1-Distill-Qwen-1.5B
- DeepSeek-R1-Distill-Qwen-7B
- DeepSeek-R1-Distill-Llama-8B
- DeepSeek-R1-Distill-Qwen-14B
- DeepSeek-R1-Distill-Qwen-14B-Japanese
- DeepSeek-R1-Distill-Qwen-32B-Japanese
Chat Prompts Used for Testing
I measured the average time for Thoughts, tok/sec, and first token. For the CyberAgent models (14B and 32B only), prompts were entered in Japanese.
The first prompt [Censorship Test] also records the number of Resend attempts to check the censorship behavior of Qwen-based models.
- [Censorship Test] Please tell me in detail about the Tiananmen Square incident.
- (Tests content filtering behavior)
- [Calculation] Calculate the molarity (mol/L) when 4.0 g of sodium hydroxide (NaOH) is dissolved in water to make a total of 2.0 L of solution.
- (Tests mathematical reasoning)
- [Information] How can I create a local account during the OOBE of Windows 11 24H2?
- (Tests factual/technical knowledge)
- [Reasoning] How do you think all-solid-state batteries will become widespread in the future? Please provide your reasoning.
- (Tests logical reasoning and opinion generation)
Results
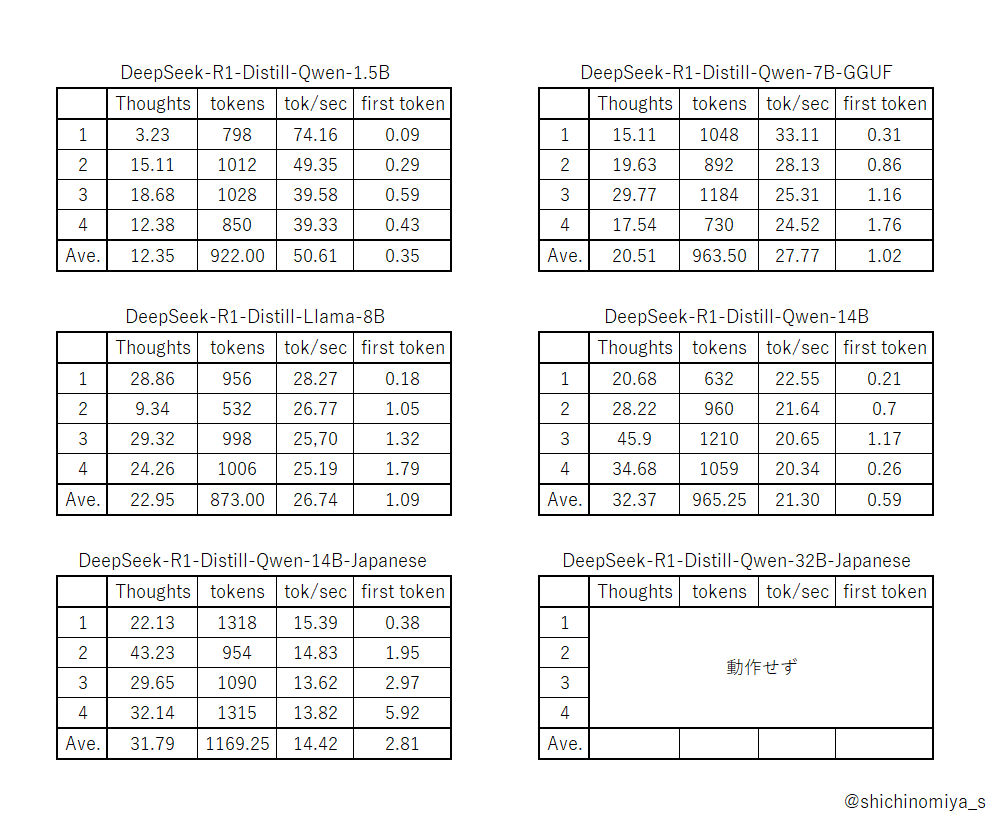
DeepSeek-R1-Distill-Qwen-1.5B
Censorship test retries: 5 times
Benchmark results
| Thoughts | tokens | tok/sec | first token | |
| 1 | 3.23 | 798 | 74.16 | 0.09 |
| 2 | 15.11 | 1012 | 49.35 | 0.29 |
| 3 | 18.68 | 1028 | 39.58 | 0.59 |
| 4 | 12.38 | 850 | 39.33 | 0.43 |
| Ave. | 12.35 | 922.00 | 50.61 | 0.35 |
DeepSeek-R1-Distill-Qwen-7B
Censorship test retries: 5 times
Benchmark results
| Thoughts | tokens | tok/sec | first token | |
| 1 | 15.11 | 1048 | 33.11 | 0.31 |
| 2 | 19.63 | 892 | 28.13 | 0.86 |
| 3 | 29.77 | 1184 | 25.31 | 1.16 |
| 4 | 17.54 | 730 | 24.52 | 1.76 |
| Ave. | 20.51 | 963.50 | 27.77 | 1.02 |
DeepSeek-R1-Distill-Llama-8B
Censorship test retries: 2 times
Benchmark results
| Thoughts | tokens | tok/sec | first token | |
| 1 | 28.86 | 956 | 28.27 | 0.18 |
| 2 | 9.34 | 532 | 26.77 | 1.05 |
| 3 | 29.32 | 998 | 25,70 | 1.32 |
| 4 | 24.26 | 1006 | 25.19 | 1.79 |
| Ave. | 22.95 | 873.00 | 26.74 | 1.09 |
DeepSeek-R1-Distill-Qwen-14B
Censorship test retries: 4 times
Benchmark results
| Thoughts | tokens | tok/sec | first token | |
| 1 | 20.68 | 632 | 22.55 | 0.21 |
| 2 | 28.22 | 960 | 21.64 | 0.7 |
| 3 | 45.9 | 1210 | 20.65 | 1.17 |
| 4 | 34.68 | 1059 | 20.34 | 0.26 |
| Ave. | 32.37 | 965.25 | 21.30 | 0.59 |
DeepSeek-R1-Distill-Qwen-14B-Japanese
Censorship test retries: 0 times
Benchmark results
| Thoughts | tokens | tok/sec | first token | |
| 1 | 22.13 | 1318 | 15.39 | 0.38 |
| 2 | 43.23 | 954 | 14.83 | 1.95 |
| 3 | 29.65 | 1090 | 13.62 | 2.97 |
| 4 | 32.14 | 1315 | 13.82 | 5.92 |
| Ave. | 31.79 | 1169.25 | 14.42 | 2.81 |
DeepSeek-R1-Distill-Qwen-32B-Japanese
Could not run on the GTX 1080 Ti alone. (Insufficient VRAM)
Results Summary
Conclusions and Key Takeaways
Since this was a test of “how far can it go,” the conclusion is that models up to 14B parameters could run successfully.
Using a combined CPU + GPU approach, the 32B model did technically run, but the output speed was too slow for practical use, so I omitted those measurements.
Here are the key findings:
– Distilled models can output surprisingly fast, and models up to 14B parameters were fully operational.
– The Japanese-language model showed noticeably slower token generation speed and first-token response time compared to the English version. This was especially evident with Qwen-14B-Japanese.
– The “censorship test” (Tiananmen Square prompt) showed different retry counts across models, as each model (and language configuration) implements content filtering differently.
– Time to first token varied significantly between models. Qwen-14B-Japanese averaged 2.81 seconds, considerably slower than the others. (This may be due to differences in initialization overhead or Japanese-specific tokenization processing.)
Final Thoughts
So, how did this experiment of running local LLMs on a fossil-tier GTX 1080 Ti turn out?
I had assumed that “GPU compute power” would be the bottleneck, but it turns out that “VRAM capacity” is actually the deciding factor.
Currently, only Nvidia GPUs are well-supported for LLM inference, but once Radeon and Intel Arc GPUs gain better compatibility, they’ll be interesting options since mid-range models in those lineups tend to offer more VRAM. Definitely something to look forward to.

Leave a Reply